The Review Bottleneck: AI Writes Code Faster Than Teams Can Review It
AI can write code fast while PRs wait for review. Track queue size, review time, and cost, then test clear gates and better handoffs.
 Axiom Studio October 19, 2026 6 min read
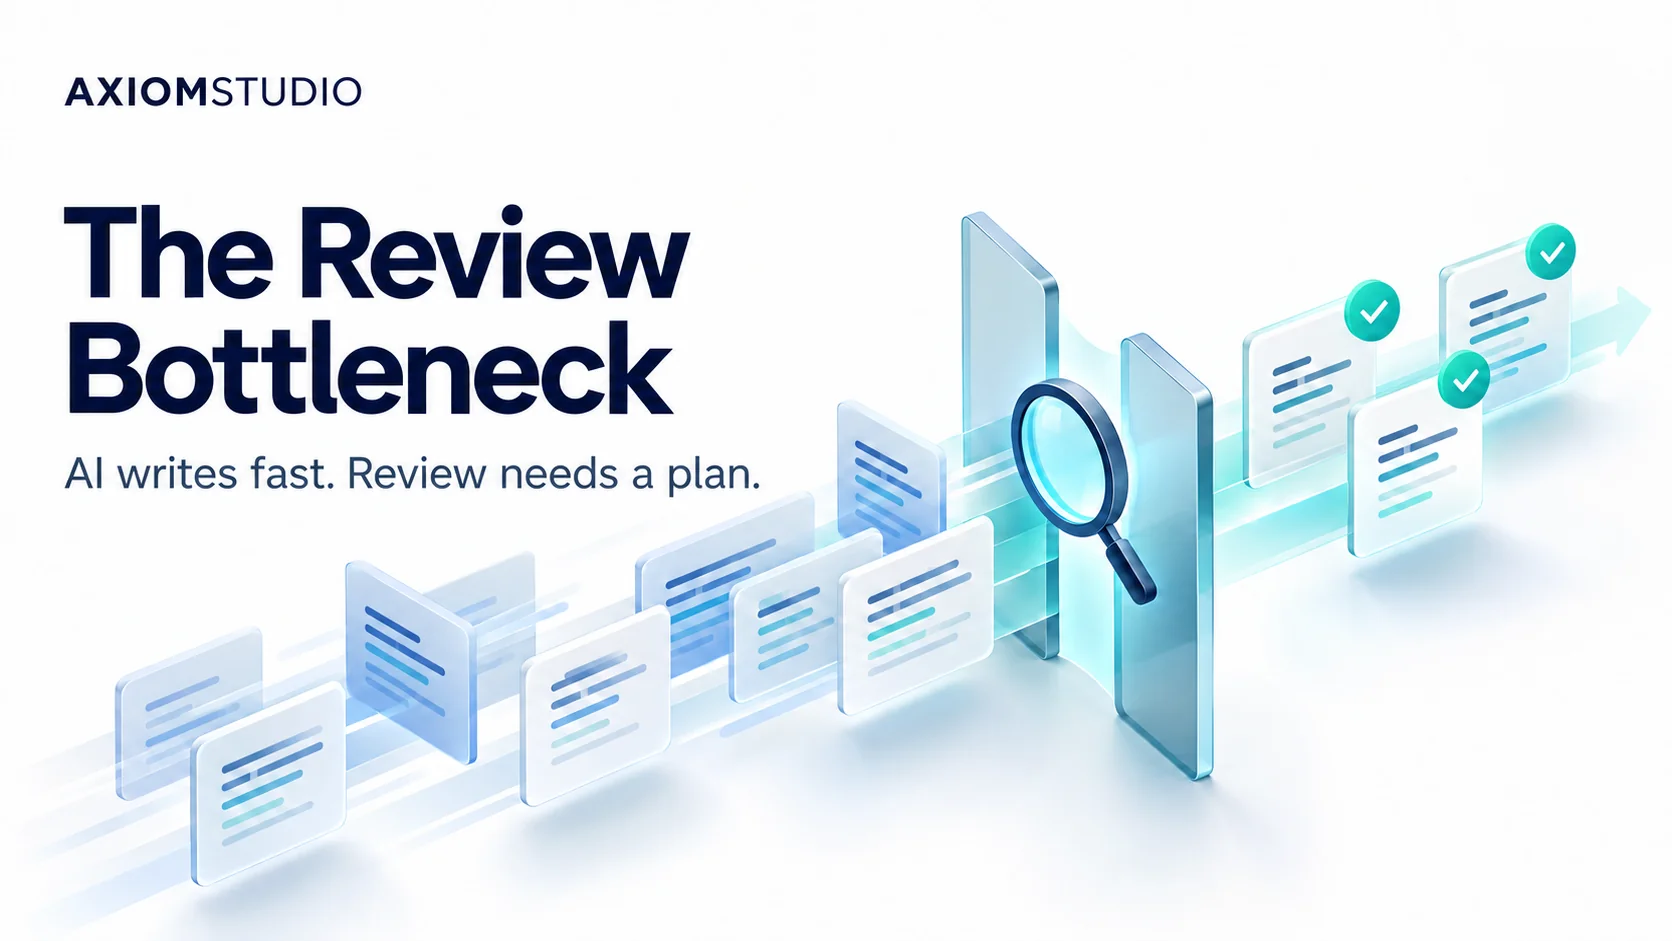
An AI agent finishes a patch in minutes. The pull request waits two days for a person to read it.
The code is ready. The team is not.
This is an example, not an Axiom result. It shows a risk worth checking: faster code writing can move the delay into review. A pull request, or PR, asks the team to accept a code change. More PRs do not help users until those changes are checked and shipped.
The fix starts with the queue. Measure what enters it, what leaves it, and how long work waits. Then set clear review rules for people and agents.
What the research shows—and what it does not
A July 2026 study followed 802 developers and 196,212 PRs at one company. The authors report that output per developer reached 2.09 times its earlier level. The load per reviewer roughly doubled. Automated review became more common than human review, while merge and revert rates stayed steady.
The research paper is a case study, not proof that every team will see the same gains. AI use was not randomly assigned. The authors do not claim exact cause and effect.
For managers, the useful signal is the shift in work. A team can write more code while asking each reviewer to handle more changes. Track your own queue before copying someone else’s targets.
Watch three trends together
First, count PRs that become ready for review each week. Separate draft work from work that a reviewer can act on. Also count merged PRs and open PRs still waiting.
Next, track PR size. Record changed lines and files, but separate generated files, lockfiles, and code you must read. A tiny change to access rules may need more care than a large text edit. Size is a clue, not a risk score.
Last, track review delay in stages:
- Ready to first useful human review: how long the change waits for a person.
- First review to final approval: time spent fixing issues and checking again.
- Approval to merge: time held by builds, release rules, or other gates.
Track bot feedback on its own. An instant bot comment should not hide a long wait for a human. Choose whether to count business hours or all hours, and use the same rule each week.
Use the median for a typical PR. Also track the slowest ten percent. Averages alone can hide old work stuck at the back of the queue.
See the queue grow before it hurts
Consider a made-up team that starts with 10 open PRs. Each day, 12 new PRs become ready and eight are merged. With no other exits, the queue gains four a day. After five days, it holds 30.
Those numbers are an example, not a benchmark. The lesson is simple: a team cannot keep adding work faster than it finishes it.
Before adding another coding agent, ask who can review its output. Set a limit on open work. When the queue reaches that limit, help finish existing changes before starting more.
Give each PR a named owner and a backup reviewer. Reserve time for review during the day. Start with a small trial and adjust it using the queue data.
Make each change easier to check
Ask for one clear purpose per PR. Keep a bug fix separate from a broad cleanup when the two can stand alone. Do not split a change so far that each part is unsafe or makes no sense on its own.
Every PR should explain the problem, the chosen fix, and what could go wrong. It should include tests and any known gaps. If an agent wrote the code, the author still owns that explanation.
A useful handoff might say: “This stops duplicate orders when a request is retried. The test sends the same request twice. Both calls return the same order ID.”
That is easier to check than “AI fixed checkout.” It gives the reviewer a claim to test.
Put checks before the merge
Use fast repeatable checks for formatting, types, and known test cases. Let an AI reviewer suggest issues that need a closer look. Then send the change to a person who owns the affected area.
Set stronger checks for changes to access, billing, private data, or data storage. Require the right owner to approve those changes. A green test run does not prove that a feature meets the user’s need.
Keep the rules clear: who may approve, which checks must pass, and what happens after a new commit. Recheck changed code. Record any allowed bypass and why it was needed.
Our AI operations guide covers the work of running and governing agents. Review gates belong in that work, with a named owner and a clear path for problems.
Do not turn bot comments into a new queue
A review bot can create work as well as save it. Track which findings lead to useful fixes. Mark repeats and false alarms. Group several comments about the same root cause.
Do not score a reviewer by the number of comments it writes. A short review that finds a real fault can be more useful than a long list of style tips.
Keep enough evidence to trace a finding: the file, changed lines, rule, and result of the follow-up check. Our AI observability guide explains why records of agent actions matter.
Measure cost per accepted change
Count tool fees, model use, build runs, retries, and paid review time. Divide the total by changes that meet your team’s checks. Keep task size and risk in view so a small fix is not treated like a major upgrade.
For example, 15 minutes of review at an assumed staff cost of $60 an hour is $15. Twenty-five minutes is $25. A low model bill may not matter much if a poor handoff adds ten minutes of review. These are planning figures, not measured savings.
Use AI FinOps to connect spend with useful output. Look for fewer repeat fixes and less waiting, not just cheaper tokens.
Run a two-week review trial
Start with one repo. In week one, record PR arrivals, size, wait time, review effort, and fixes found after merge. Save the sample size and the mix of tasks.
In week two, add one change: a limit on open work, a better PR handoff, or a named review slot. Keep the other rules steady where you can.
Compare similar tasks. Note staffing changes, urgent incidents, and release freezes. Report both typical and slow reviews. A short trial can guide the next step; it does not prove a lasting gain.
Explore VibeFlow to connect planning, coding, security review, and QA. Start with one flow and measure the path from a ready PR to an accepted change. Faster writing is useful when review can keep up.
Written by
Axiom Studio